- ID-LoRA generates a talking video where the voice matches a ~5-second reference clip and the face matches a first-frame image, in one audio-video pass with no per-speaker training. Prompts use three tags:
[VISUAL],[SPEECH](exact transcript),[SOUNDS](delivery plus ambience). - Pick the right tool: ID-LoRA for new words with no footage, Dub-It when the footage exists and only the words change, A2V when the performance is already recorded.
ID-LoRA is an In-Context LoRA that makes an LTX model generate a talking video in which the voice matches a short reference clip and the face matches a reference image, in a single audio-video pass. You give it three inputs: a text prompt, a first-frame image, and roughly five seconds of the speaker's audio. No per-speaker training is needed.
The method is a research project built on LTX-2 and LTX-2.3, accepted to ECCV 2026, and published with code, checkpoints, and a ComfyUI integration in the ID-LoRA repository.
This guide explains how it works, how to prompt and configure it, and where it fits next to the tools that ship with LTX-2.5.
How does ID-LoRA work?
ID-LoRA works by adapting the joint audio-video backbone of LTX instead of chaining a voice model and a video model. Per the project README, four design choices do the work:
- Reference conditioning. The reference audio is encoded by the Audio VAE and concatenated with the noisy target latents along the sequence dimension. The video stream uses first-frame conditioning, which anchors the face.
- Negative temporal positions. Reference audio tokens get negative positions in the RoPE space, so the model separates them cleanly from the target timeline. This addresses the positional entanglement that arises in cross-video settings, where reference and target share no temporal correspondence.
- Identity guidance. A classifier-free guidance variant on the audio stream contrasts predictions with and without the reference, amplifying timbre, rhythm, and pronunciation while leaving scene content to the text prompt.
- Audio-only in-context. Only reference audio tokens are prepended. No video reference tokens are added, which keeps the adapter light and the video stream free to follow the prompt and first frame.
ID-LoRA's LoRA is rank 128 and targets audio self-attention, audio-video cross-attention, and audio feed-forward layers. It was trained on about 3,000 pairs on a single GPU. On the paper's CelebV-HQ cross-video split it scored a speaker similarity of 0.477 against 0.391 for the strongest cascaded baseline, and the authors report it beating both cascaded pipelines and a leading commercial model on lip sync.
ID-LoRA vs Dub-It vs A2V
ID-LoRA, Dub-It, and audio-to-video solve different identity problems, and picking the wrong one wastes a render. The difference is what already exists before you start.
If you need the speaker to say something new with no footage of them saying it, that is ID-LoRA. If the footage exists and only the words change, use Dub-It. If the performance is already recorded and you want it kept intact, A2V drives the picture from it. For prompting speech itself, see directing dialogue and acting.
The three-part ID-LoRA prompt
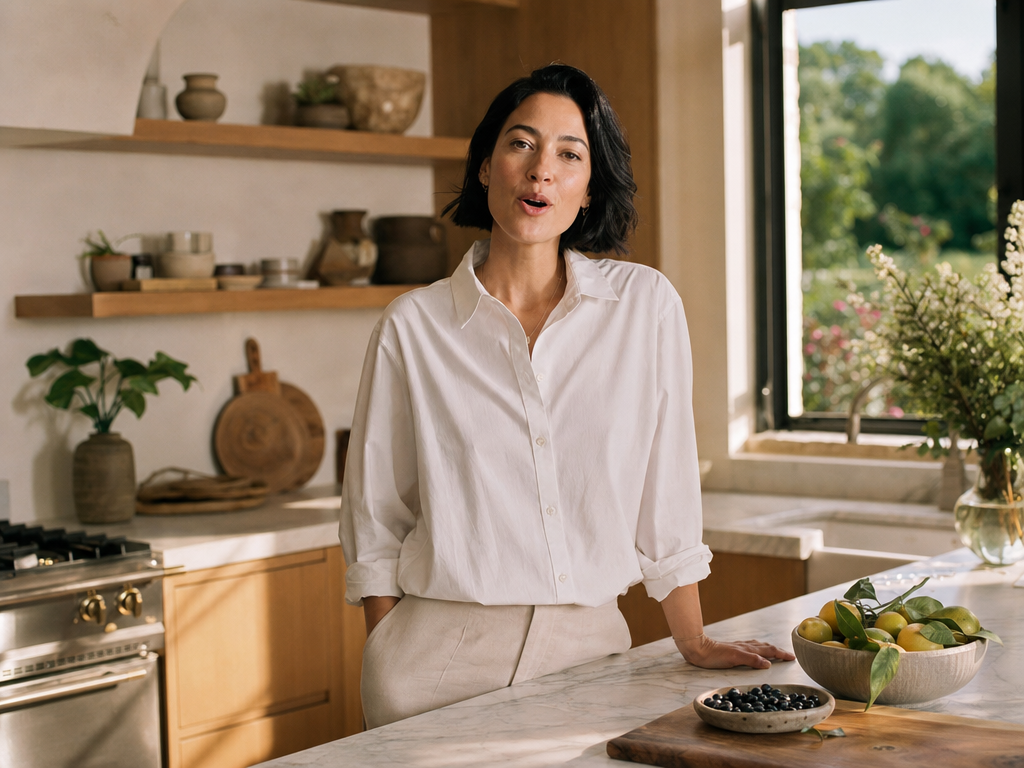
ID-LoRA prompts use three tagged sections, and each one steers a different part of the output:
[VISUAL]: A medium shot of a woman with short black hair in a white blouse, standing in a modern kitchen with warm lighting, speaking calmly to the camera.
[SPEECH]: Hello everyone, welcome back to the channel.
[SOUNDS]: The speaker has a calm, conversational tone at moderate volume, close to the microphone. Soft birdsong drifts in from an open window.
- [VISUAL] carries shot type, appearance, clothing, setting, and lighting. State that the person is speaking, or the model may produce a voice-over.
- [SPEECH] holds the exact transcript, never a summary.
- [SOUNDS] controls both delivery (tone, volume, mic distance) and ambience. This is where you move the same voice from a quiet room to a street.
The first-frame image should agree with [VISUAL]. A close-up reference paired with a wide-shot description asks the model to reconcile two framings, which is likely to weaken the face anchor.
Settings that decide the result
ID-LoRA settings live in the repo's inference scripts. The documented defaults set video guidance to 3.0, audio guidance to 7.0, identity guidance to 3.0, the seed to 42, and the frame count to 121. The higher audio guidance is deliberate, since the audio stream carries the identity transfer.
Reference length is the setting people get wrong most. The README warns that clips shorter or longer than about five seconds may degrade voice identity transfer, so trim a long interview to one clean five-second stretch rather than feeding the whole thing. The frame rule is the same one the LTX VAE enforces, (F-1) % 8 == 0, so 121 frames is valid and 120 is not.
Hardware per the ID-LoRA README: Python 3.11+, CUDA 12.x, 24GB+ VRAM, with 48GB recommended for two-stage runs. The two-stage script generates at 512x512, then refines at 1024x1024. On LTX-2.3, a Two-Stage HQ mode uses the Res2s sampler with 15 steps instead of 30. LTX-2.5's own system requirements differ (CUDA 12.7 or newer, Python 3.12 or newer, and an 80GB GPU as the target with 32GB supported under quantization), so check which stack you are installing.
How do you run it in ComfyUI?
ComfyUI runs ID-LoRA natively. Upstream ComfyUI merged ID-LoRA support for LTX in PR #13111, adding the LTXVReferenceAudio node for reference-audio speaker identity transfer, and the original ID-LoRA weights load without conversion. The project also ships a custom node, ID-LoRA-LTX2.3-ComfyUI, with one-stage, two-stage, and two-stage HQ modes. The IC-LoRA walkthrough covers the general node pattern.
From the command line, the two-stage LTX-2.3 run looks like this:
bash
uv run python ID-LoRA-2.3/scripts/inference_two_stage.py \
  --lora-path models/id-lora-celebvhq-ltx2.3/lora_weights.safetensors \
  --reference-audio reference_speaker.wav \
  --first-frame first_frame.png \
  --prompt "[VISUAL]: ... [SPEECH]: ... [SOUNDS]: ..." \
  --output-dir outputs/two_stage \
  --quantize
Two published checkpoint families exist, trained on CelebV-HQ and on TalkVid. The LTX-2.3 packages share module names with the LTX-2 ones, so switch the pyproject.toml workspace to ID-LoRA-2.3/packages/* and re-sync rather than installing both.
Does ID-LoRA work with LTX-2.5?
ID-LoRA publishes checkpoints for LTX-2 (19B) and LTX-2.3 (22B) and recommends the LTX-2.3 version.
There is a specific reason not to assume it ports cleanly. ID-LoRA's text conditioning was trained against the Gemma 3 encoder that LTX-2 and LTX-2.3 use, while LTX-2.5 ships a different, custom Gemma 4 encoder. LTX's model card notes that most LTX-2.3 LoRAs and IC-LoRAs run unchanged on LTX-2.5, with exceptions to validate before production, but an adapter whose whole job is conditioning on audio and text against the older encoder is exactly the kind of case most likely to be an exception. Treat ID-LoRA on LTX-2.5 as unvalidated and run it on LTX-2.3.
If you want identity control trained on LTX-2.5 itself, the LTX Trainer has the building blocks. ID-LoRA is itself trained through that trainer, using a reference-audio latents directory and its own audio_ref_only_ic strategy with the negative temporal positions and identity guidance described above, so reproducing it on 2.5 means porting that training recipe rather than loading a checkpoint. For the IC-LoRA concept in general, see what IC-LoRAs are and the LoRA training overview.
Consent and labeling
Consent comes first with any tool that reproduces a real voice and face. The ID-LoRA authors release it for research and ask users to get explicit consent from any identifiable person, label all output as AI-generated, and never use it to deceive, harass, or defraud.
Build those steps into the pipeline rather than adding them later: keep a signed release with every reference clip, and burn a synthetic-media label into deliverables. This is also a licensing matter, since both the ID-LoRA code and the underlying LTX weights come with terms that govern use.
Summary
ID-LoRA is an In-Context LoRA for LTX-2 and LTX-2.3 that generates a talking video whose voice matches a roughly five-second reference clip and whose face matches a first-frame image, with no per-speaker training. It prepends reference audio tokens with negative temporal positions and adds an identity guidance term on the audio stream. Prompts use [VISUAL], [SPEECH], and [SOUNDS] sections, and frame counts must satisfy (F-1) % 8 == 0. ComfyUI supports it natively through the LTXVReferenceAudio node.
Start with the LTX-2.3 CelebV-HQ checkpoint, a clean five-second voice clip, and a consented reference image.

