AI text-to-video model
Language defines the video. Prompts control motion, composition, and visual flow.





Key capabilities

Prompt-driven generation
Video is generated from text prompts, with language controlling actions, camera movement, environments, visual style, and motion.

Cinematic output
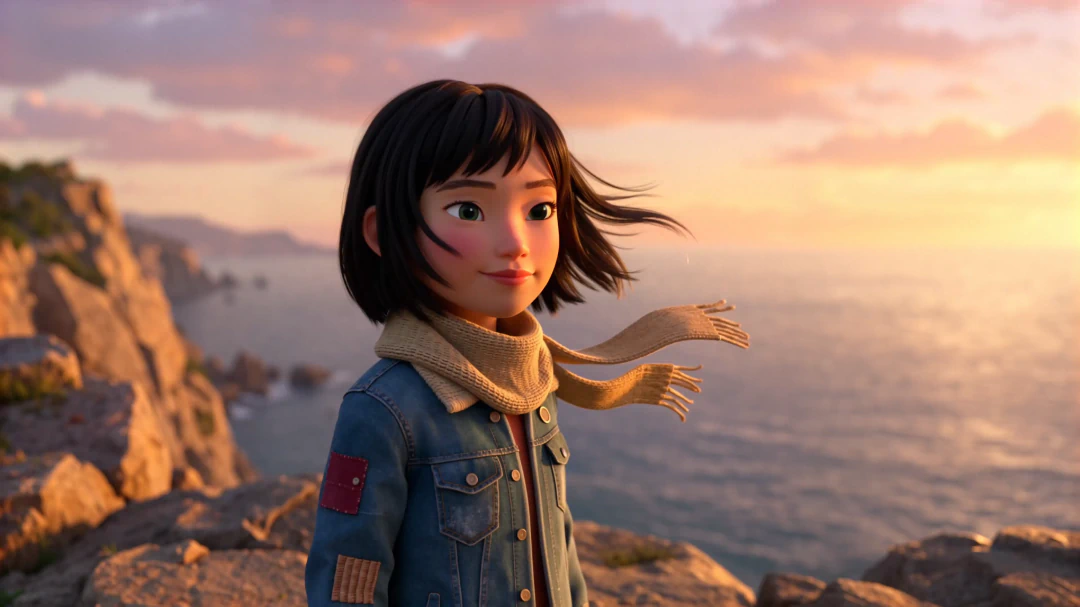
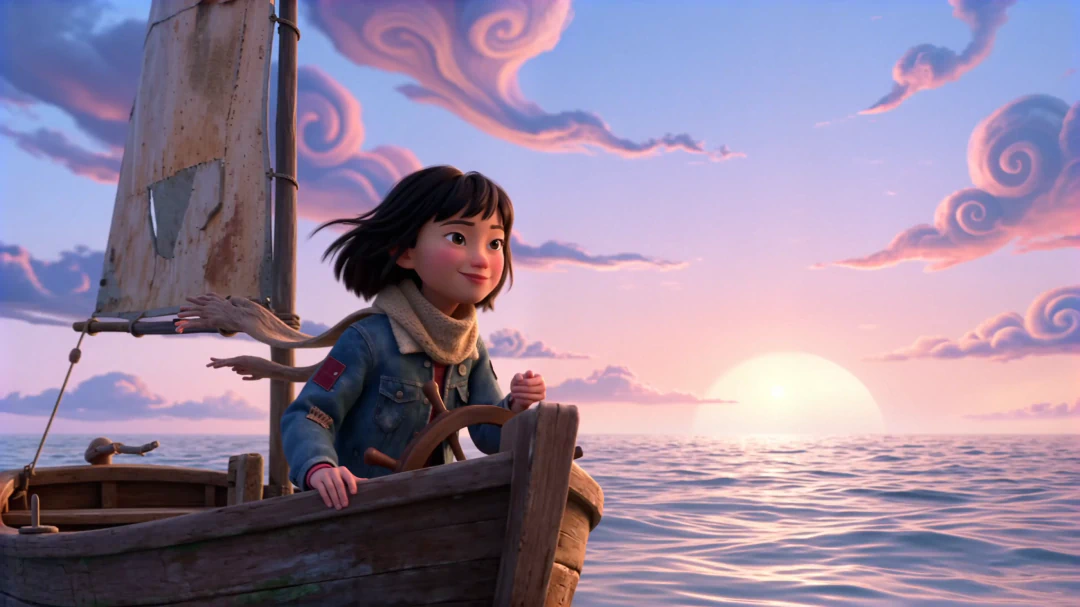
Professional-grade visual quality at native 4K, up to 50 FPS. Built for cinematic motion and visual clarity, not low-res demos.
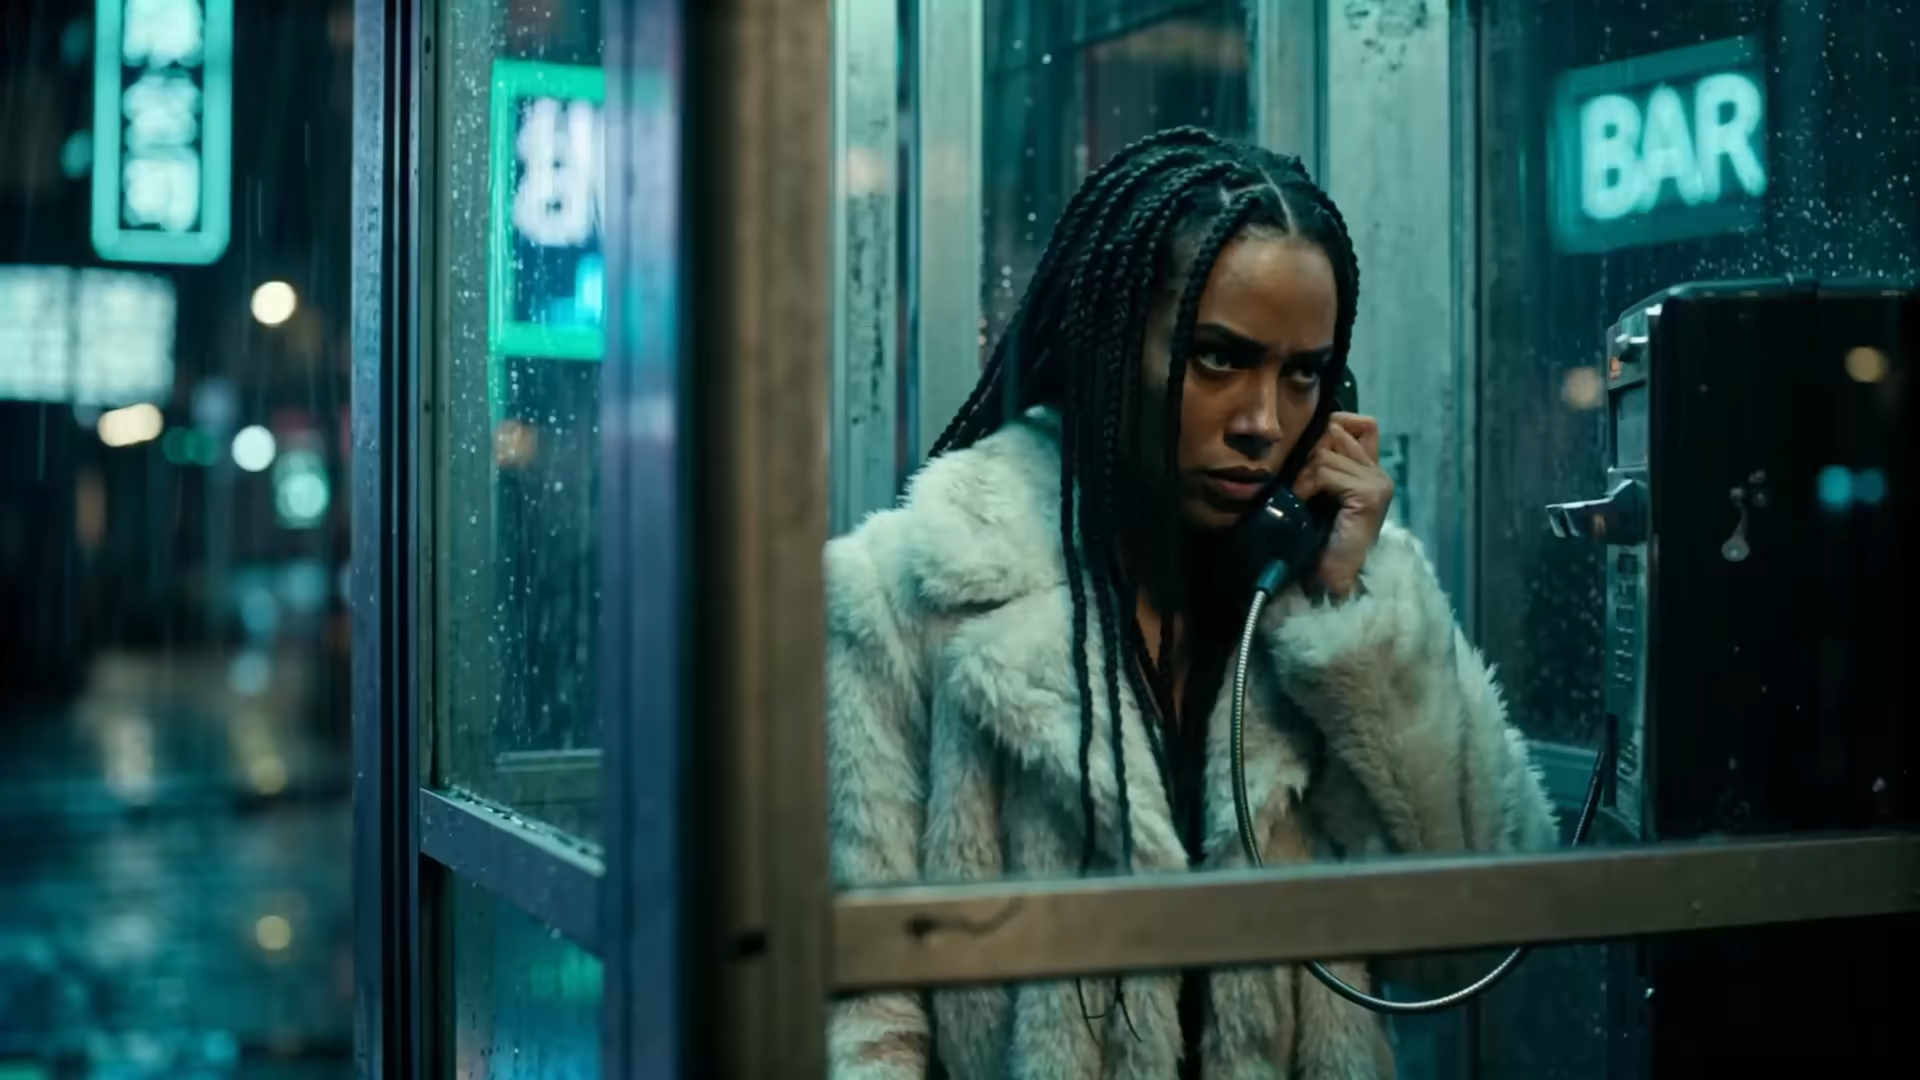
Content creation without manual animation
Generate videos directly from text descriptions for storytelling, creative exploration, and concept development. No keyframing required.


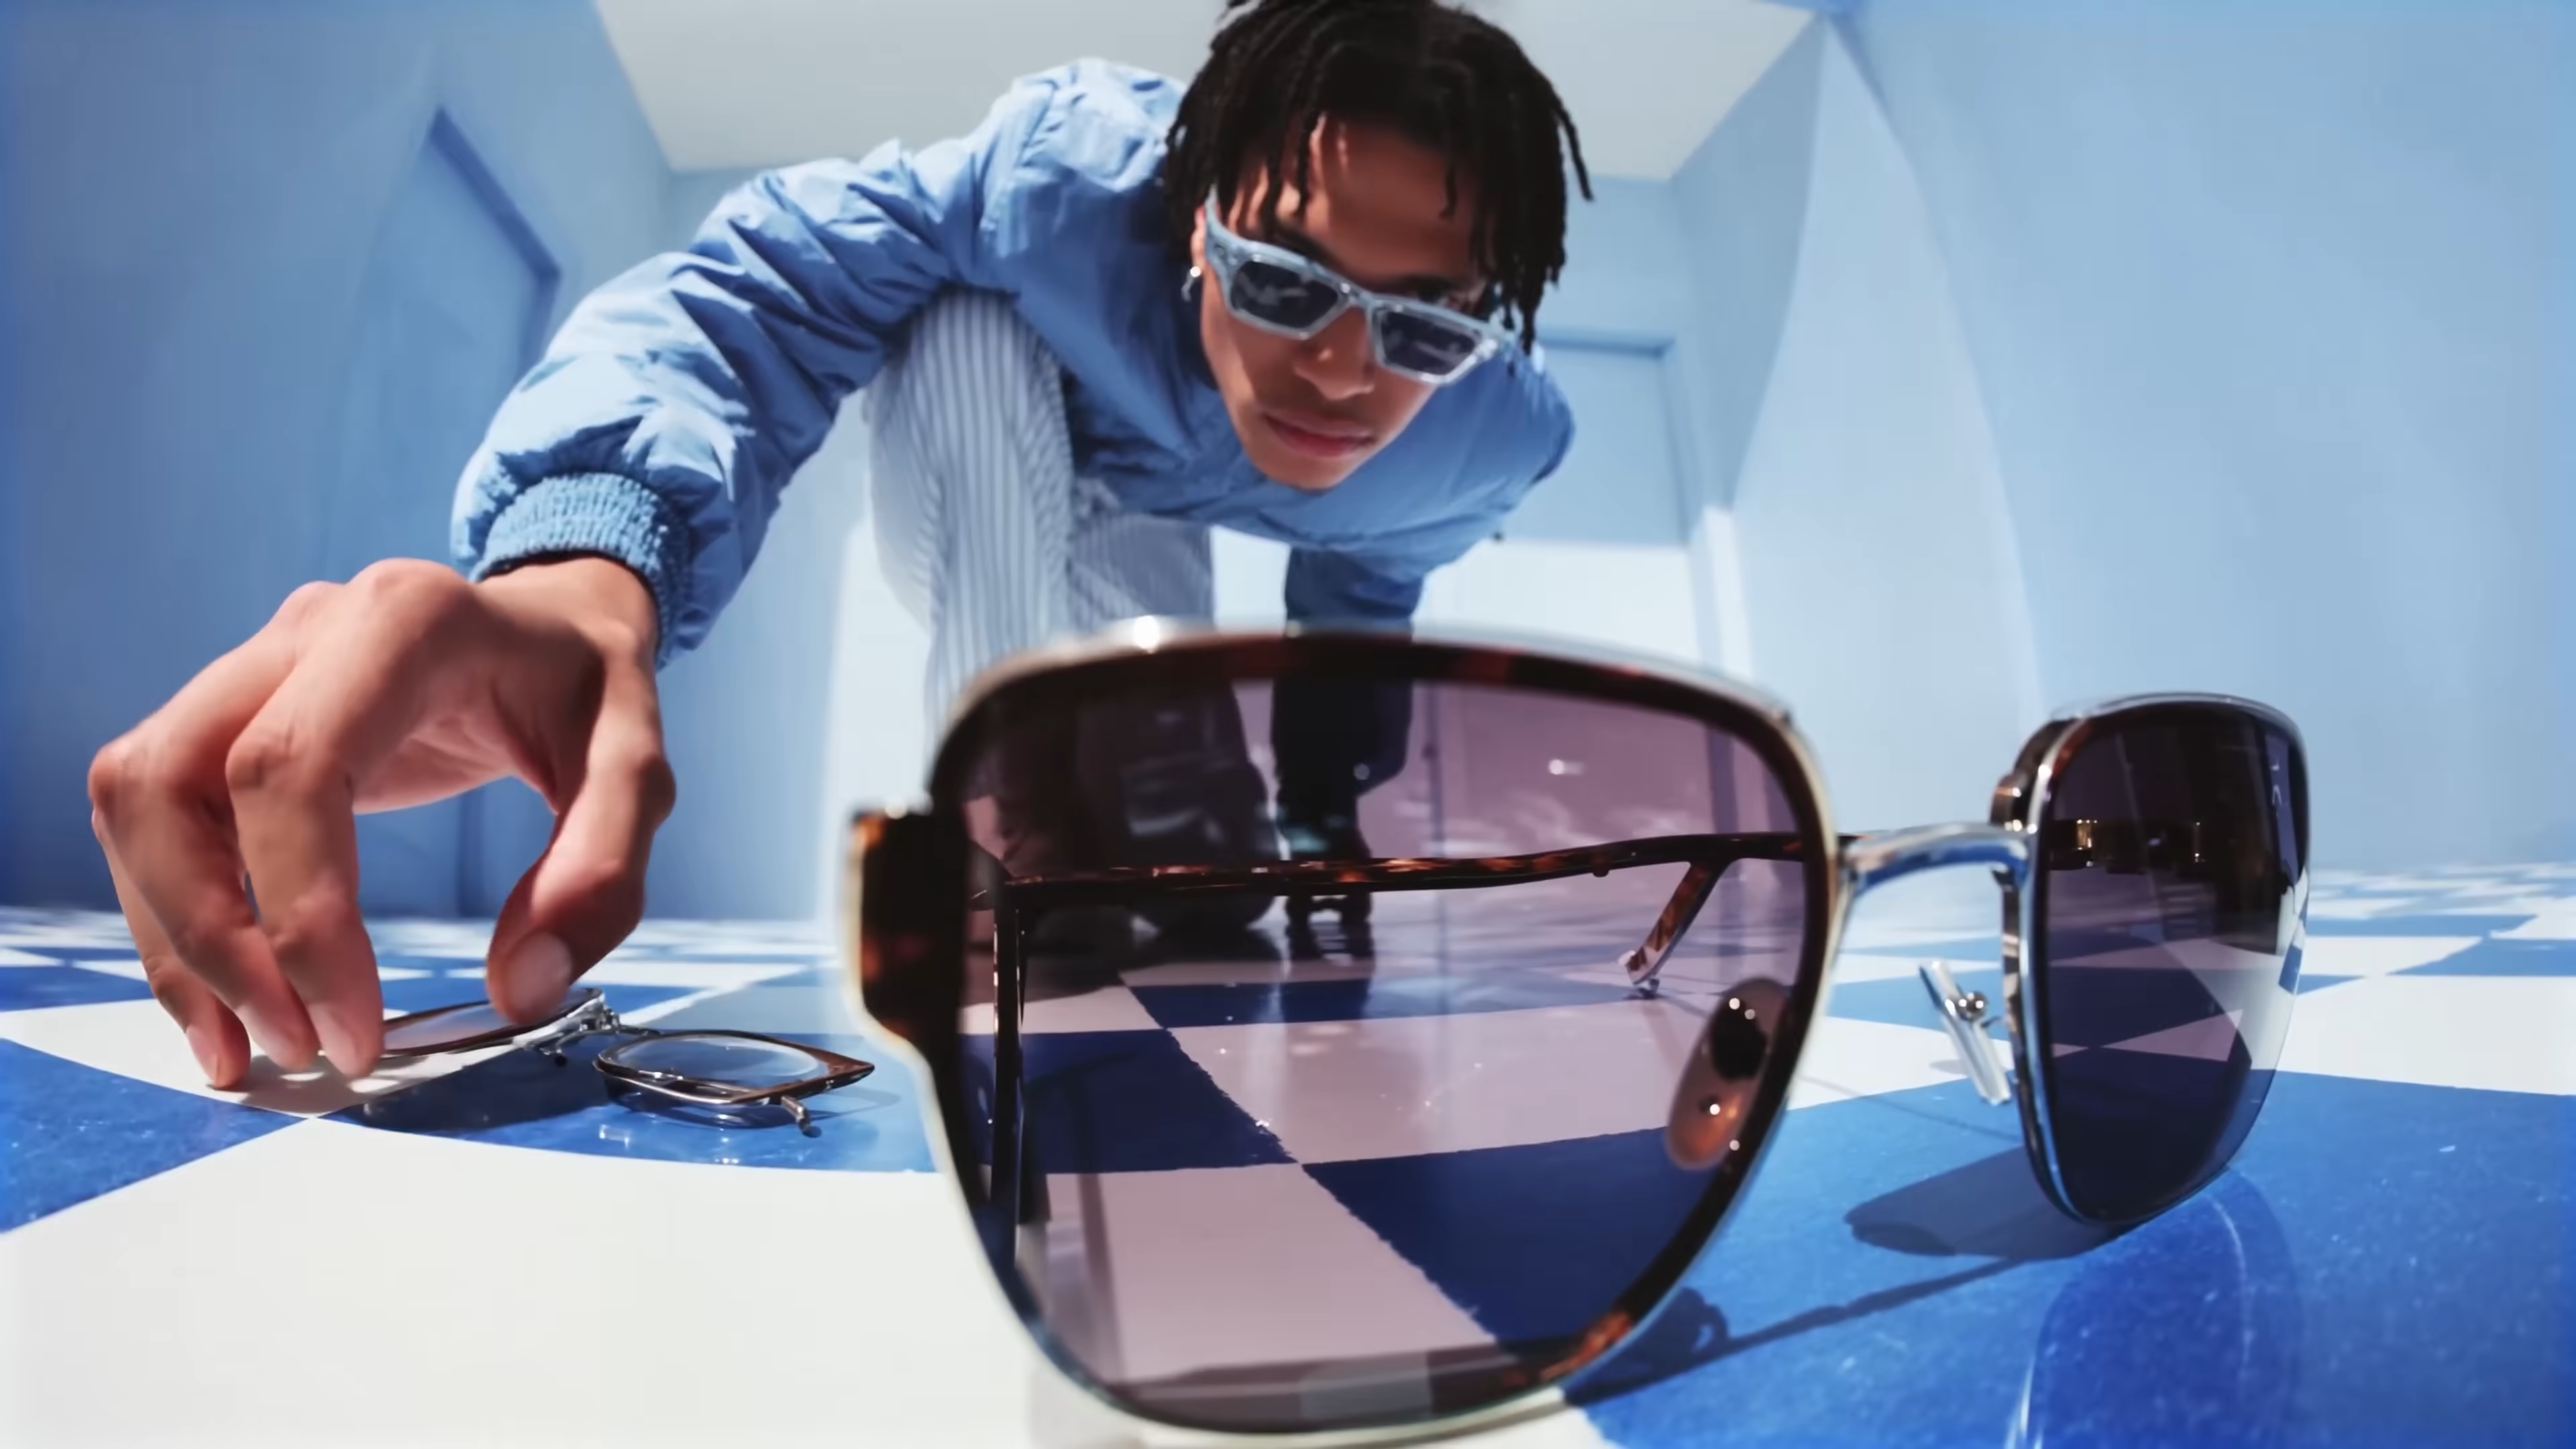
Marketing & brand content
Produce promotional videos, product scenes, and branded content from text descriptions. Fast iteration, repeatable results, and scalable production.
Previsualization & storyboarding
Translate scripts and shot descriptions into video previews to explore narrative flow, pacing, and framing choices before committing to production.
Research & model experimentation
Study prompt adherence, temporal reasoning, and generative behavior with a production-grade text-to-video foundation model.
Designed for real-world deployment
A production-ready text-to-video AI model for teams building scalable, controllable video generation workflows.
Product teams, AI startups, and developers building AI-powered video features. Add production-grade video generation as a product capability, not a research project. One API, production-ready results, and no custom orchestration.
Brands, agencies, and creative teams producing high volumes of content. Turn existing assets into video at scale. Faster iteration, lower production cost, and more output from what you already have.
Teams that require full control over deployment and data. Run video generation in your own environment. On-premises, no cloud dependency, and full infrastructure ownership.
Platforms powering creative tools with multiple AI models. Upgrade your video output with a best-in-class engine. Improve generation quality, retain users, and differentiate with a model built for production, not prototypes.
How it works
Input
Describe the scene you want to generate using a detailed text prompt. Optionally add visual conditioning to control actions, camera movement, layout, and overall style.
Technical characteristics:
- Text prompt (required): Detailed description of actions, scenes, camera behavior, and visual style
- Optional conditioning: Images or keyframes to anchor composition or layout
- Generation parameters: Resolution, FPS, duration, seed, inference steps
Output
Receive an MP4 video generated from your text prompt, with coherent motion, consistent visuals, and structure aligned to your described scene.
Technical characteristics:
- MP4 video generated from text
- Up to ~20 seconds per generation
- Coherent motion, style consistency, and prompt-aligned structure
Text-to-Video
Optimized for higher fidelity and increased temporal stability. Best for production-ready output and final renders.
- 1280×720 — $0.04/sec
- 1920×1080 — $0.08/sec
- 2560×1440 — $0.16/sec
- 3840×2160 — $0.32/sec
- Ideal for client-facing content or polished deliverables.
- Higher compute level → higher visual quality.
Text-to-Video
Optimized for higher fidelity and increased temporal stability. Best for production-ready output and final renders.
- 1280×720 — $0.12/sec
- 1920×1080 — $0.17/sec
- 2560×1440 — $0.25/sec
- 3840×2160 — $0.39/sec
- Ideal for client-facing content or polished deliverables.
- Higher compute level → higher visual quality.
What users are building with LTX

FAQs
What is the Text-to-Video model in LTX?
An AI video generation model that produces video directly from text prompts. Language conditions motion, composition, and visual flow.
How does LTX-2.5's Text-to-Video work?
The model interprets detailed text prompts—actions, scenes, camera movement, style—and translates them into coherent video sequences with consistent motion and structure.
How is LTX-2.5 different from other text-to-video models?
Built for cinematic quality and production workflows, not demos. High-resolution output, strong prompt adherence, and scalable inference for real-world deployment.
What video quality can I expect?
High-fidelity generation with native 4K output and high frame rates. Smooth motion and professional-grade visual quality.
How long can videos be?
Up to ~20 seconds per generation. Longer sequences through chained generations and composable workflows.
Can I control camera movement through text?
Yes. Prompts specify camera angles, movement, pacing, transitions, lighting, and scene dynamics. Fine-grained control through language alone.
Is text-to-video available via API?
Yes. Available through the LTX-2.5 API, designed for developers, platforms, and enterprise teams integrating video generation into products.
Is the LTX-2.5 Text-to-Video model open source?
Yes. Code and model weights available on GitHub and Hugging Face. Inspect, run locally, fine-tune, and integrate into custom workflows.
Can text-to-video combine with images or keyframes?
Yes. Hybrid workflows where text prompts work alongside images or keyframes to anchor composition, maintain continuity, or guide structure.
Is LTX-2.5 suitable for production?
Yes. Built for predictable behavior, high-quality output, and scalable deployment in real-world production environments.
